
AI in Research: The Answers Hiding in Plain Sight

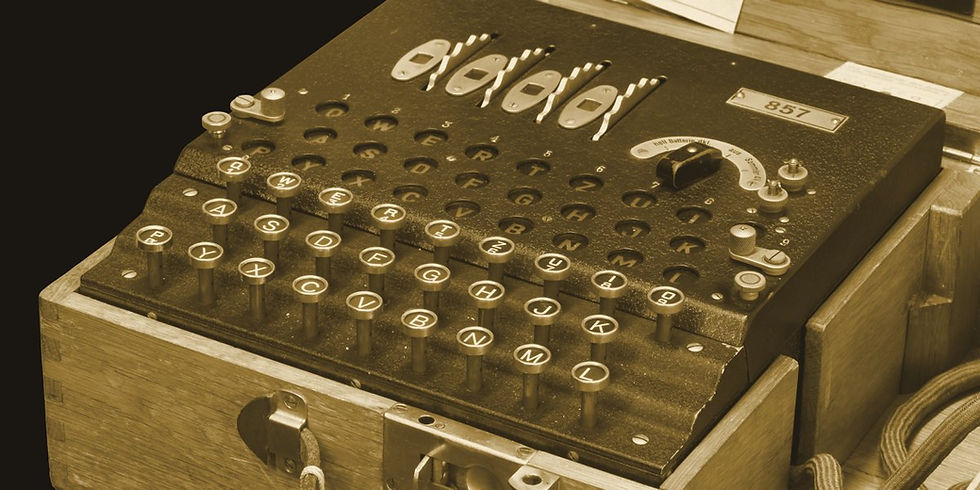
Image: "Enigma-IMG 0487-black" by Rama (CC BY-SA 2.0 fr) via Wikimedia Commons, recoloured.
Welcome to this week's scan of how AI is reshaping research, curated from Nature, Science, PNAS and the leading business journals.
AI is finding the answers hiding in plain sight. Who checks them?
Two stories this week describe the same shift from different ends. Science reports on BootLoops, software that let researchers quickly find and attack problems in 22 disciplines. The toolkit grew out of Harvard physicist Matthew Schwartz's time as a visiting researcher at Anthropic, where Claude built tools problem by problem. Per coverage of the project, roughly 400 candidate problems were narrowed to 36 manuscripts with 19 coauthors in three months, on topics from Medicare star ratings to sunspots, often by carrying a known method from one field into another where nobody had thought to apply it. Meanwhile Nature reports that non-experts are using large language models to break historical ciphers: one, with no cryptography background, had a model select an unsolved 1941 Enigma message, write an Enigma simulator and test more than four billion settings overnight until a solution emerged.
The catch is the same in both cases. Schwartz found it hard to judge when the model overstated findings in unfamiliar fields, so domain experts decided which results were worth pursuing; many early results were technically correct but scientifically unremarkable. And cryptographers told Nature their inboxes are flooded with requests to validate AI-produced solutions, many of them false positives from people who do not understand cryptanalysis. A conceptual paper in Strategic Entrepreneurship Journal by Haiyang Zhang, Robert Wuebker and Jay Barney gives this a strategy lens: opportunities that rest on competitive neglect may lose their value when GenAI makes hidden rents legible to everyone, while opportunities created under genuine Knightian uncertainty are ones GenAI cannot fully resolve.
Why it matters: For researchers, "low-hanging fruit nobody noticed" is becoming a shrinking asset; AI is very good at transferring existing methods into neglected corners. What stays scarce is judgment: knowing which result matters, and being able to verify it. If you use AI to scout problems, budget for expert validation up front, report how candidates were filtered (400 to 36 is itself a finding), and expect reviewers and editors to face the same validation flood that cryptographers already do.
More from this week
AI-made ads work best when they don't look like AI
Working with Taboola ahead of its GenAI Ad Maker launch, the authors compared 4,633 'sibling ads': AI-generated and human-made images launched by the same advertisers, in identical campaign settings, at the same time, spanning over 369 million impressions and 2.5 million clicks. They found no detectable average click-through disadvantage for AI images, but AI images outperformed human-made ones when they did not 'look like AI'. Intriguingly, features AI tends to produce (sharper, clearer images with larger faces) were read by consumers as human-made, while heavy aesthetics, lower warmth and intense colour saturation signalled AI.
An AI 'panel of physicians' tested on sequential diagnosis
This Science paper builds an interactive benchmark in which a diagnostician starts from a brief presentation and must choose which information and tests to acquire, so both accuracy and workup cost can be measured. An AI system simulating a panel of physicians, which continually revises its differential and selects cost-effective tests, achieved 83.2% accuracy on New England Journal of Medicine clinicopathological cases and 80.3% on MIMIC-IV emergency admissions, against 36.1% and 46.8% for generalist physicians. The authors stress these are controlled benchmark results, but the design itself (scoring the process, not just the answer) is a useful template for evaluating AI in any sequential decision task.
How AI rewires venture capital, task by task
This conceptual paper develops a mechanism-based account of how data and AI reshape venture capital, an industry built on geographic and social proximity. It offers propositions on sourcing (AI can widen the funnel beyond local networks and warm introductions), selection (faster, more consistent diligence, but models trained on past deals may favour ventures that resemble previous investments and miss novel ones) and post-investment work, where data can partly replace monitoring but value-added support stays relationship-intensive. A ready-made set of testable hypotheses for entrepreneurship and finance scholars.
Steering LLMs from the inside, more reliably
Activation steering (directly manipulating a model's internal activations to push its outputs toward a concept) is notoriously brittle. The authors propose an attention-guided framework that automatically selects relevant tokens, handles heterogeneous concept features and identifies the layers that matter most. On a benchmark of 512 semantic concepts it nearly doubled the number of successfully steered concepts versus the previous state of the art, across architectures up to 70 billion parameters. For researchers using LLMs as instruments, it is a reminder that model behaviour can be shifted from within, not just via prompts.
The AI safety debate is missing half the system
Responding to AI executives' recent warnings to the UN Security Council, this Science commentary argues that proposed safeguards focus heavily on evaluating and governing models while largely overlooking risks that arise when AI interacts with people and institutions. Its case is that safety must be addressed at the level of the human-AI system. That framing puts social scientists, organisational researchers and behavioural scholars squarely at the centre of AI safety research.
Brand visibility in the age of AI search
This MIT Sloan Management Review piece argues that LLM-driven search creates two distinct challenges for brands: being visible in AI answers, and being represented accurately. As zero-click responses replace links on results pages, SEO becomes entwined with generative engine optimisation (GEO) and new metrics replace traditional traffic analytics. For marketing researchers, it flags a fast-moving measurement problem with few established constructs yet.
That's this week. Forward it to a colleague who's hunting for an overlooked research question, and explore AI tools for your own research at gaiforresearch.com.


Comments